Finance
& AI.
Strategy, risk, and building with models.
Looking for roles where finance and AI overlap.
About
An undergraduate at UT Dallas working toward two B.S. degrees, one in Finance and one in Business Analytics & AI. I build applied AI systems from start to finish, with a background in finance, risk and quantitative methods.
Skills
AI
- Machine learning
- Neural networks
- RAG architectures
- NLP
Finance
- Financial modeling
- Risk management
- Quantitative analysis
- Corporate finance
- Derivatives
- Portfolio management
Also
- Financial analysis
- Compliance
- Applying AI in finance
Projects
Axton
A platform for analyzing SEC filings with AI. It uses a RAG pipeline to answer questions about 10-K, 10-Q and 8-K filings.
Live at axton.arnavprabhu.com.
Next.js / Supabase / Gemini
pi-swarm
A framework for coordinating many AI agents, built on pi.dev. The agents are organized like a three-level company with 21 specialist roles.
Works with any model, tracks cost in real time, has a live terminal UI.
Python
Doxa
A pipeline that writes equity research reports. Six specialist agents handle market data, valuation, SEC filings, sentiment, writing and editorial review.
Python
Emulsion
A 35mm film lab in the browser. Drop in phone photos and they come back as film scans, with the grain, halation and soft highlights of real film stock.
Live at emulsion.arnavprabhu.com. Everything develops on your device, so nothing gets uploaded.
Vite / TypeScript / WebGL2
Splashboard
A macOS menu bar app for Splash, a local LLM engine for Apple silicon. It installs Splash and a model, serves one OpenAI- and Anthropic-compatible endpoint, and shows live tokens per second, memory and cache.
Runs Claude Code, Codex and other coding agents on your local model for a session. Install with brew install --cask arnavprabhu/tap/splashboard.
Swift / Python / FastAPI / Preact
ArnavBench
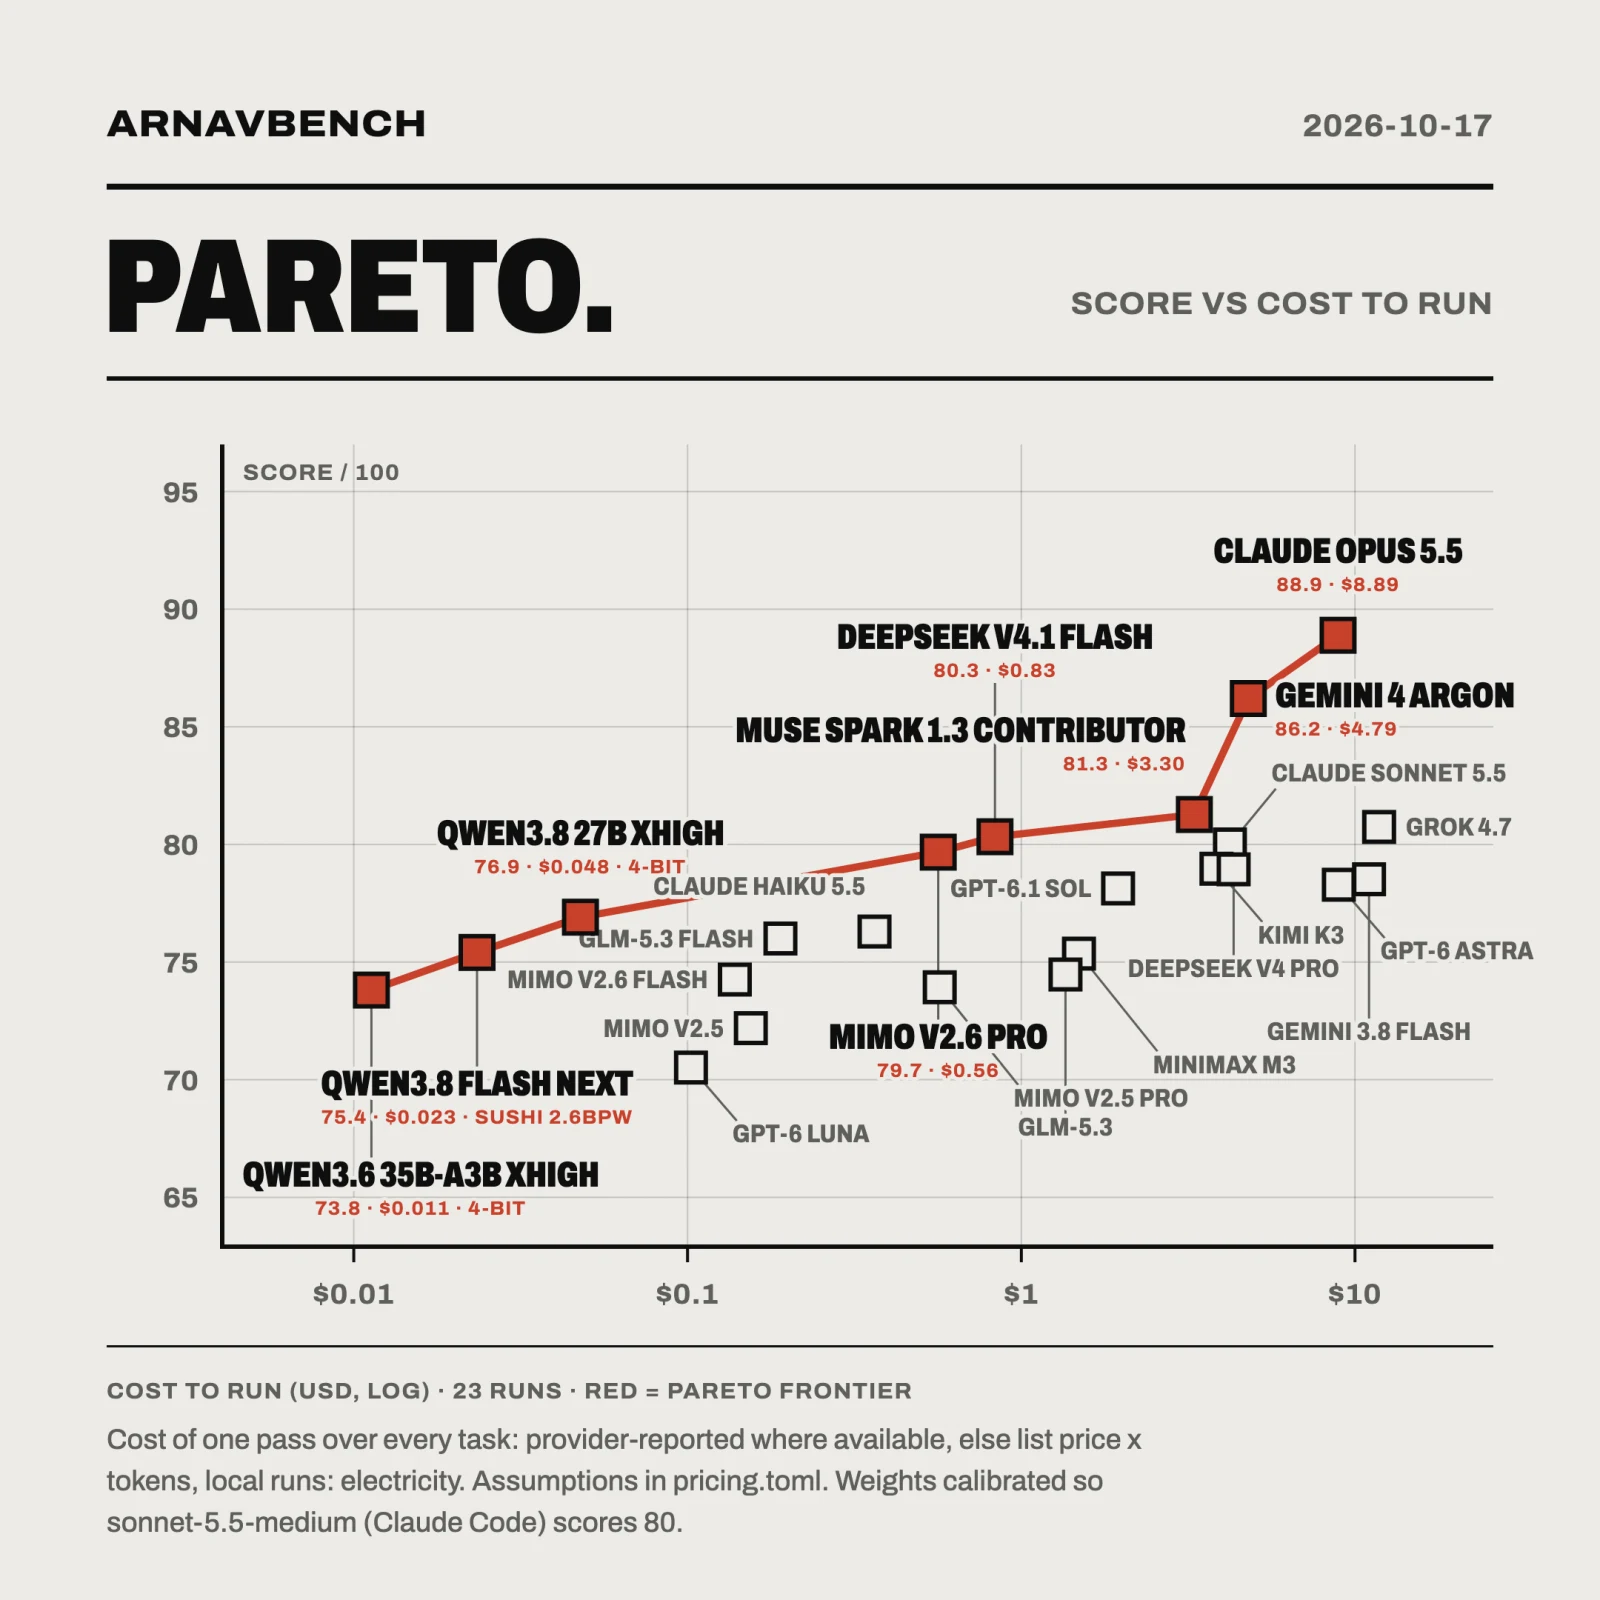
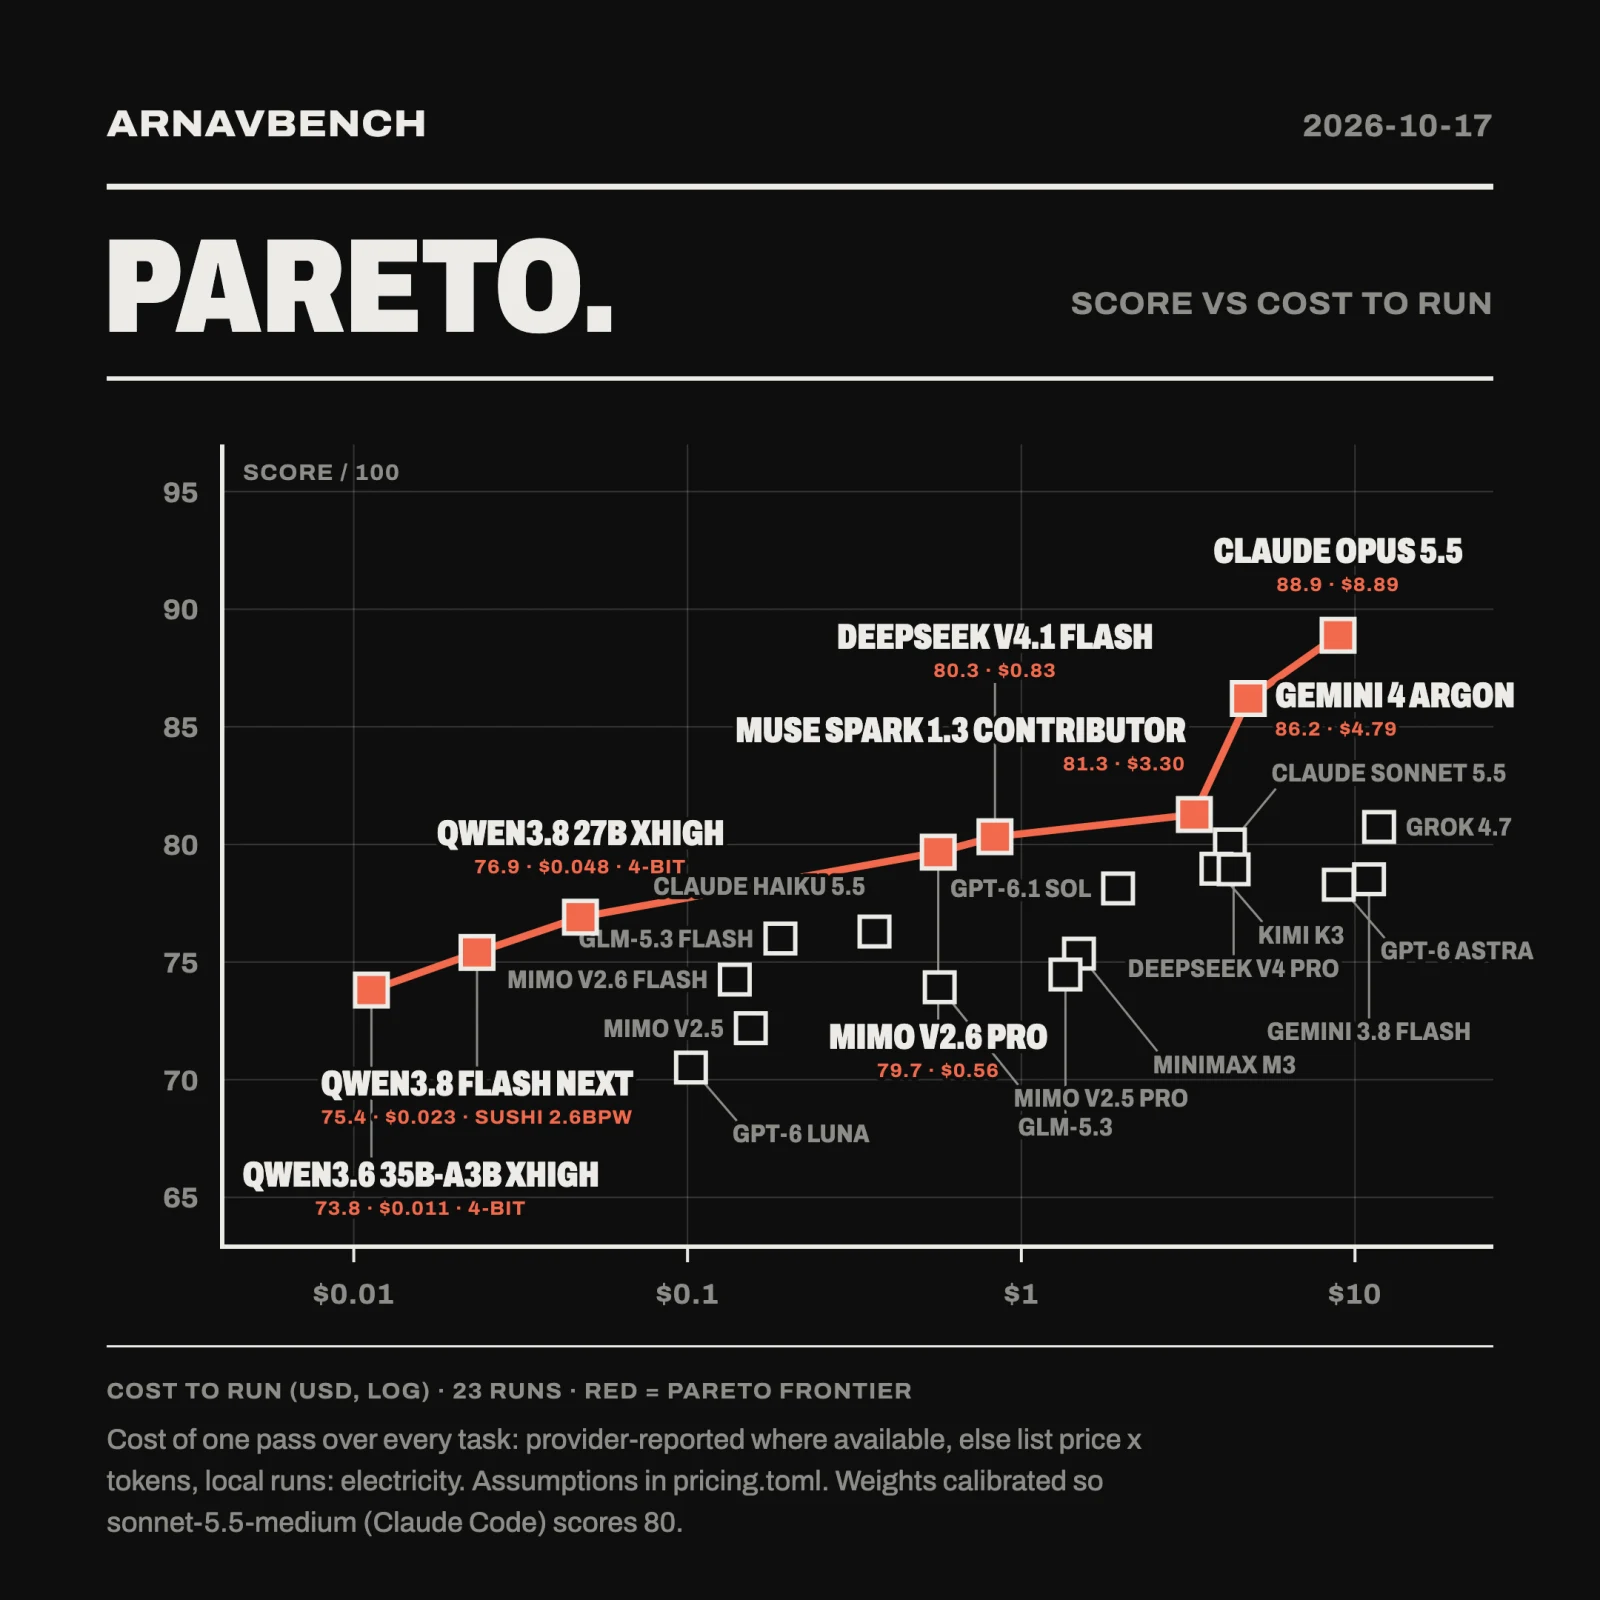
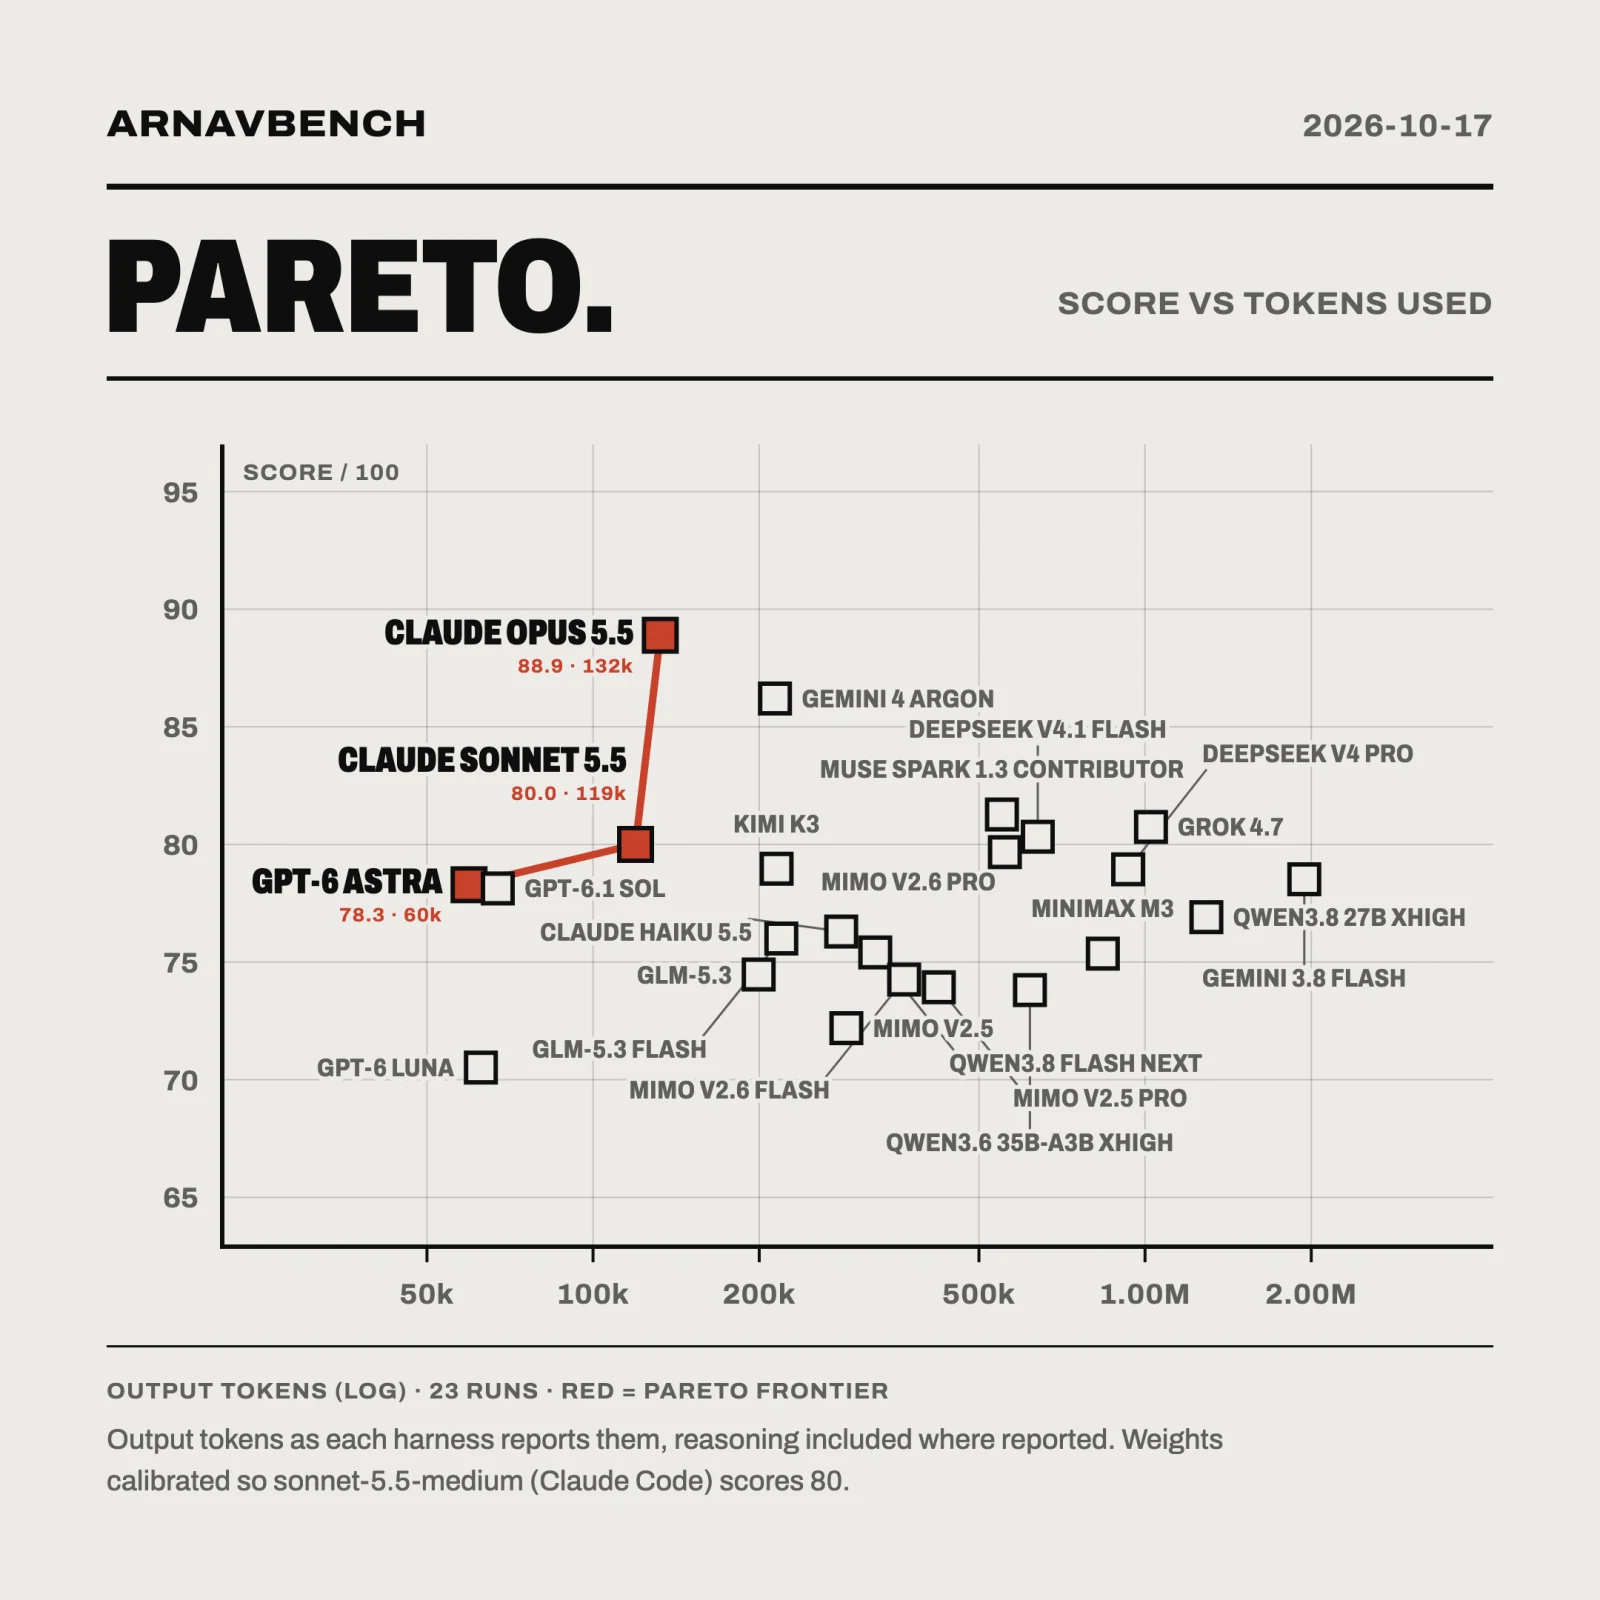
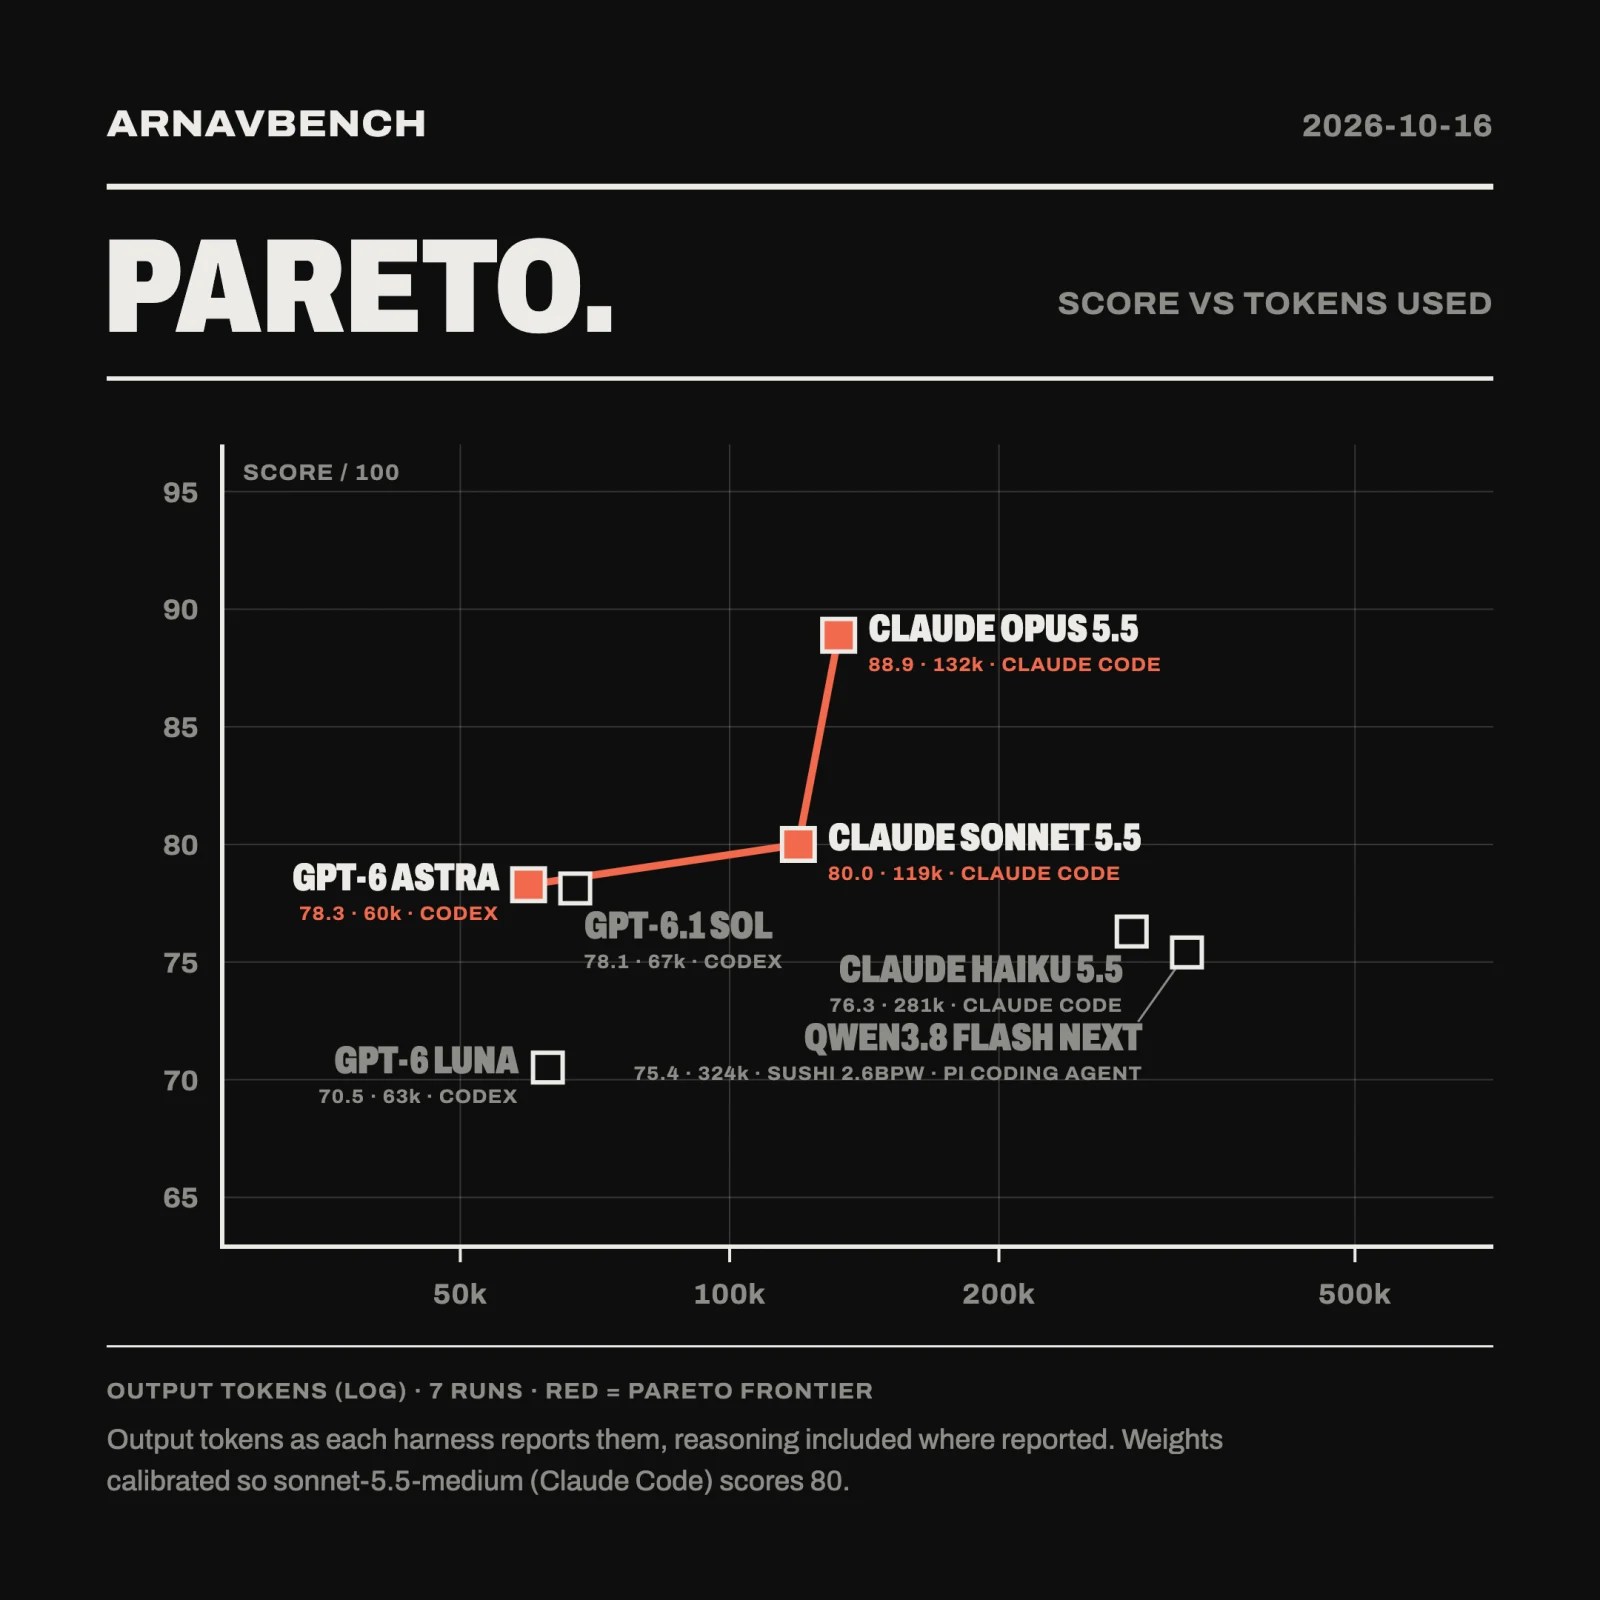
A private LLM benchmark of 198 tasks sampled from public benchmarks to match the work I hand to models: repo-level coding, tool calling, secure code, library code, instruction following, code reasoning and finance.
Each task is graded by its benchmark's official metric in a network-off sandbox. 23 runs so far, from frontier APIs to 4-bit Qwen on a laptop.
Python
Applied AI
- RAG SystemsAxton
- Multi-Agent Orchestrationpi-swarm
- Agentic WorkflowsDoxa
- Model EvaluationArnavBench
- Local InferenceSplashboard
- Production DeliveryNext.js + Supabase + Gemini